AMECxSV: Adaptive Metadata-Driven Calibration for X-Lingual Speaker Verification
· Paper · Speaker Verification / Score Calibration / X-Lingual ASV / MLP
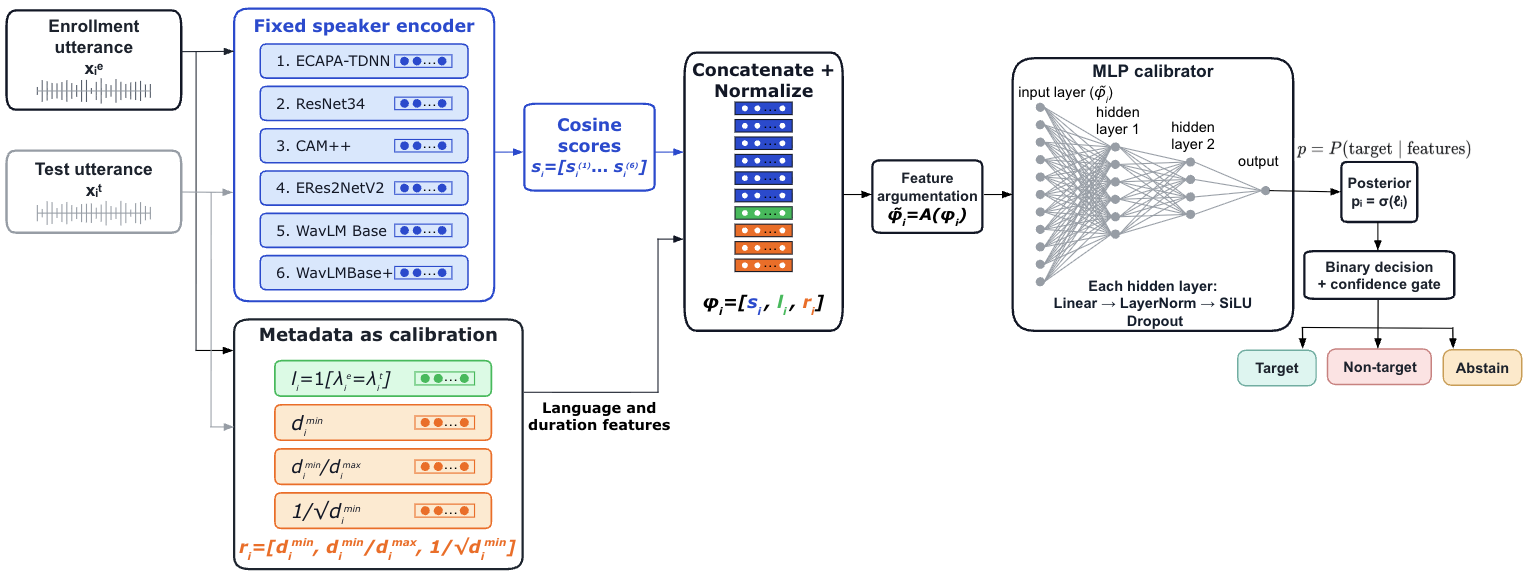
AMECxSV is a lightweight calibration backend for cross-lingual speaker verification. It fuses scores from fixed speaker encoders with trial context such as language match and utterance duration, without retraining the encoders.
On the held-out development-derived evaluation, the score-and-metadata heads improve full-coverage EER for both the official TidyVoice score source and LI-MSV. The controls also show the intended boundary: metadata improve calibration when aligned with score evidence, but are not useful as speaker evidence by themselves.